In its October 30, 2026 announcement, OpenAI said it plans to support a shared AI training preference signal for website owners. The proposed approach would let publishers, businesses, and website administrators communicate how their online content may be used to train generative AI models. The company aims to make these preferences easier to manage across multiple participating AI providers.
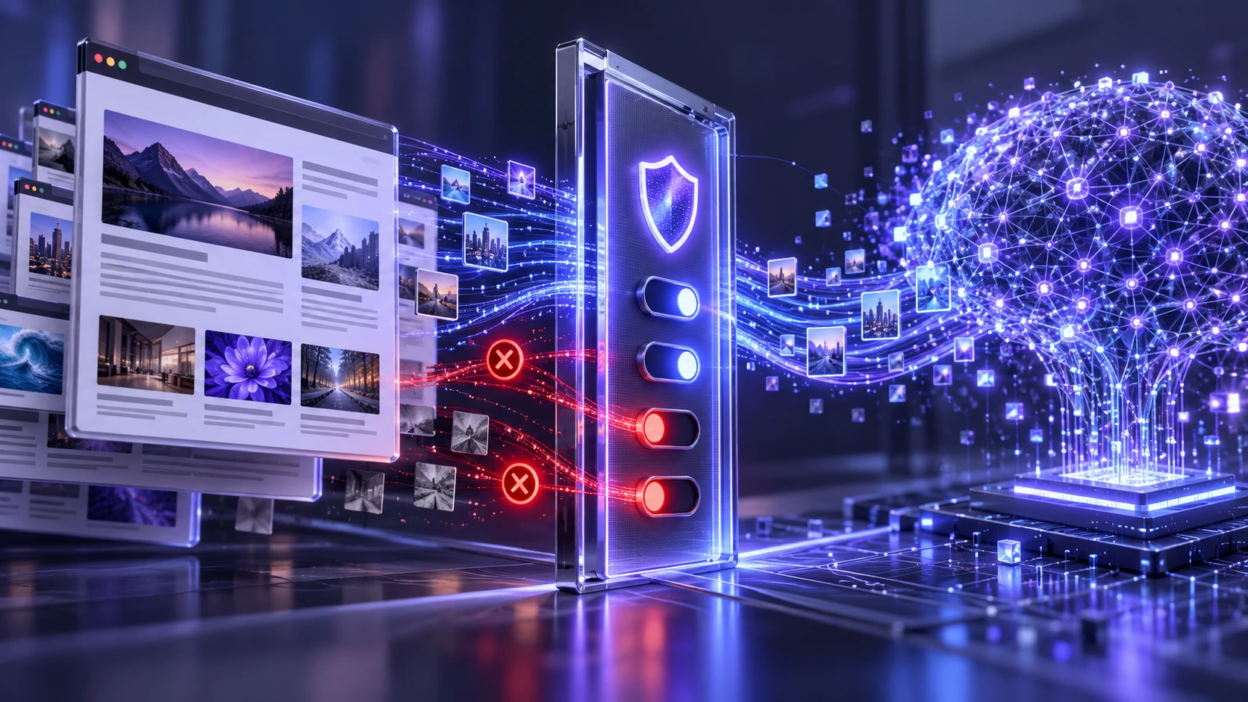
The proposed signal would let website owners express how their content may be used to train generative AI through a file called robots.txt. This file is also used to manage automated web crawlers. Unlike a general crawling restriction, the shared signal is intended to communicate preferences about AI training. Publishers could use it to express the same preference to multiple AI companies that choose to recognize it.
Website administrators currently manage separate crawler rules for different AI services. According to OpenAI’s crawler documentation, GPTBot is used to collect content that may help train generative AI models, while OAI-SearchBot supports website visibility in ChatGPT search. Publishers can restrict GPTBot while allowing OAI-SearchBot, giving them separate controls over training-related crawling and search visibility. However, managing rules across multiple AI providers can still be complicated.
The draft technical proposal describes a shared AI training preference signal that website owners could express through robots.txt. It uses a proposed policy token called __usage_ai-training, alongside existing Allow and Disallow rules, to communicate preferences for different parts of a website. The approach could reduce the need for separate instructions across participating AI providers. However, the proposal remains an Internet-Draft rather than an approved IETF standard.
AI developers use large datasets to train language models that can generate text, answer questions, and perform other tasks. TechBonafide’s guide to how ChatGPT works explains how models learn patterns from training data. Because some AI training material can come from publicly accessible websites, publishers have raised questions about copyright, permission, and how their content is collected and used.
The proposal draws on work by the IETF AI Preferences working group, which is developing ways for websites and other content providers to express preferences about how their material is used by AI systems. The working group’s broader efforts include methods for associating preferences with online content. OpenAI says it will continue participating in these discussions while preparing support for the shared signal.
OpenAI has not yet implemented support for the shared AI training signal. In its October 30 announcement, the company said it aims to introduce support in the coming months and publish further technical details. Until then, website administrators can continue using OpenAI’s existing robots.txt controls to manage individual crawlers. OpenAI has confirmed that the new system will not replace those controls.
For website owners, the planned system could make AI training preferences easier to manage. However, participation is voluntary, and the shared signal cannot force every AI company to follow a publisher’s instructions. It also does not automatically remove previously collected training data or resolve copyright disputes. Importantly, expressing an AI training preference is different from blocking search crawlers, so website owners should manage search visibility separately.
The announcement comes amid wider debates about copyright and the use of online content for AI training. TechBonafide previously reported on OpenAI and Anthropic’s AI copyright proposals in Australia, where the use of protected creative material for AI development has raised important policy questions. A shared preference signal could help publishers communicate their choices, but it would not automatically resolve copyright disputes or guarantee that every AI provider follows those preferences.
For now, website owners should continue reviewing their existing crawler settings and watch for OpenAI’s implementation update. If the shared AI training signal gains support from more providers, it could simplify how publishers communicate their content preferences. Its practical impact will depend on adoption, consistent interpretation, and how participating companies honor those choices.