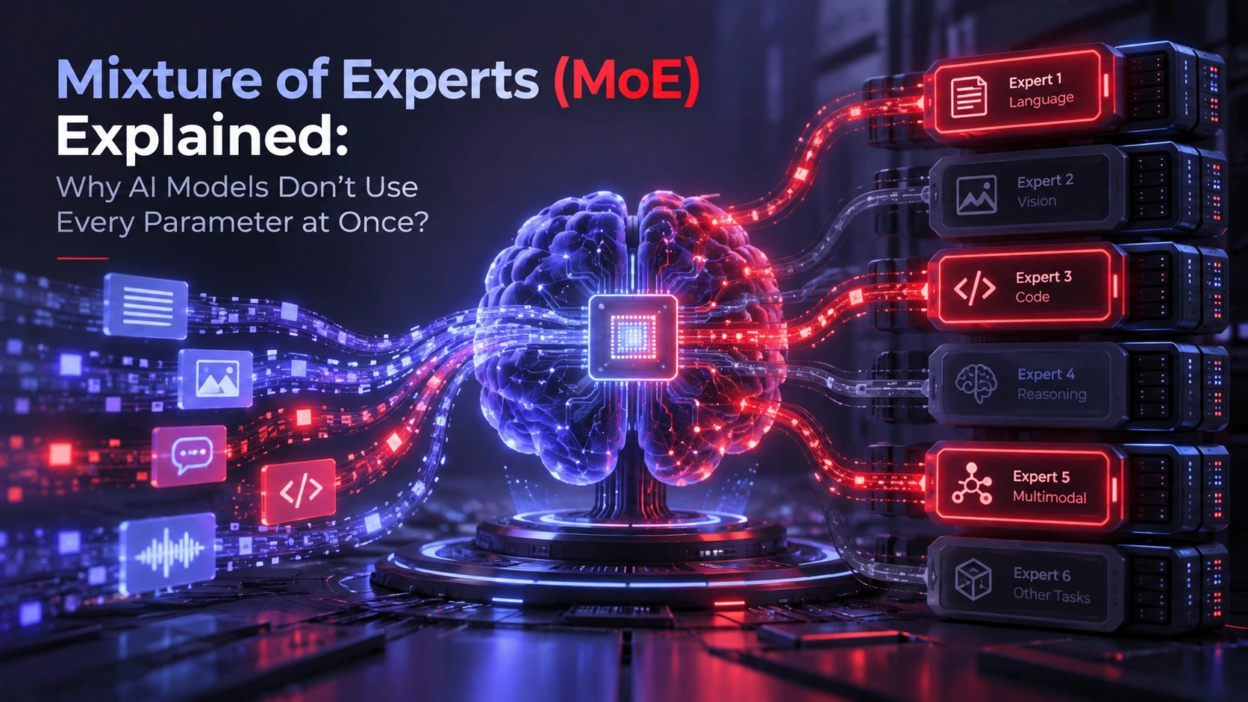
Mixture of Experts (MoE) is a sparse neural network architecture that increases a model’s total parameter capacity without activating every expert parameter for each token. Instead, a routing mechanism sends each token to a small subset of specialized expert networks, allowing the model to scale its capacity while keeping active computation lower than a similarly sized dense model.
What Mixture of Experts Means
In a dense transformer, the same feed-forward blocks are generally used for every token, so the layer’s main learned weights participate repeatedly across the sequence. As the model grows, computation and memory requirements typically increase with model size because the network does not selectively skip entire expert blocks the way a sparse MoE layer does.
MoE changes that pattern by adding multiple expert feedforward networks in certain layers. A routing component selects which experts will process each token, so only a fraction of the experts are active at once.
The modern approach builds on sparsely gated Mixture-of-Experts research, where a trainable gating network determines which subset of experts should process an input.
Why AI Models Do Not Use Every Parameter at Once?
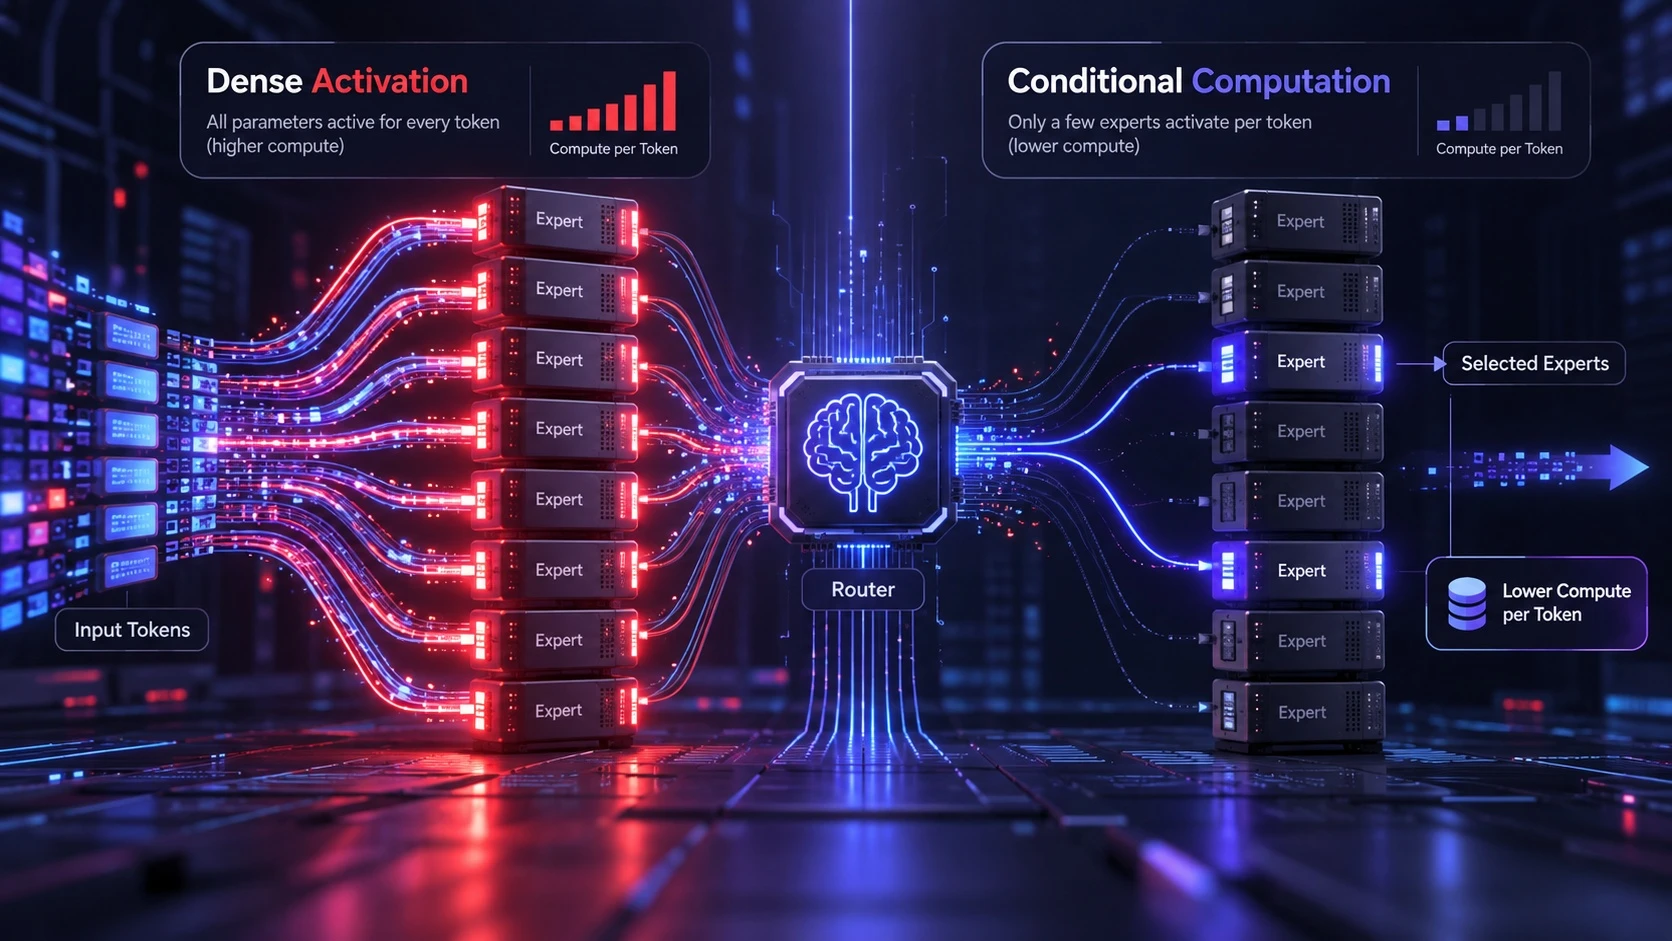
Dense activation wastes compute when many parameters contribute little to a specific token. MoE aims for conditional computation so the model spends cycles only where they help most.
This approach partially separates total parameter capacity from the amount of computation required for each token. An MoE model can therefore contain substantially more parameters while activating only a subset of them during each routing step, although communication and routing overhead still contribute to the real computational cost.
How Does Routing Work in an MoE Layer?
The router is a small network that scores each expert for each token representation. It then chooses the top experts and sends the token activations to them while skipping the rest.
Many sparse MoE architectures use top-k gating, where the router selects a limited number of experts for each token. The value of k depends on the architecture: some systems use a single expert, while others activate two or more. The selected experts process the token representation, and their outputs can then be combined according to the router’s gating weights.
For example, Mixtral 8x7B contains eight feed-forward experts in each MoE layer and routes every token to two of them. This illustrates how a model can have a large total parameter count while using only a smaller active subset during inference.
- Token Level Decisions: Each token can be routed differently, which helps when a single sequence contains multiple topics or styles.
- Top K Selection: Only a small number of experts are activated, keeping compute predictable and bounded.
- Weighted Combining: Router scores influence how much each expert contributes to the final hidden state.
- Capacity Limits: Systems enforce per expert token limits to prevent overload and keep training stable.
These mechanisms make MoE efficient, but they also introduce new engineering constraints around routing, load balancing, and communication.
Experts as Specialized Subnetworks
An expert is usually a standard feedforward block that matches the shape of the transformer layer. The difference is that there are many copies, each with its own parameters, and only some are used per token.
During training, different experts can develop different activation patterns or functional roles because the router sends them different subsets of tokens. However, these specializations are not always cleanly separated into human-readable topics, and their usefulness depends heavily on routing quality, training objectives and load balancing.
Dense Models Versus Sparse MoE Models
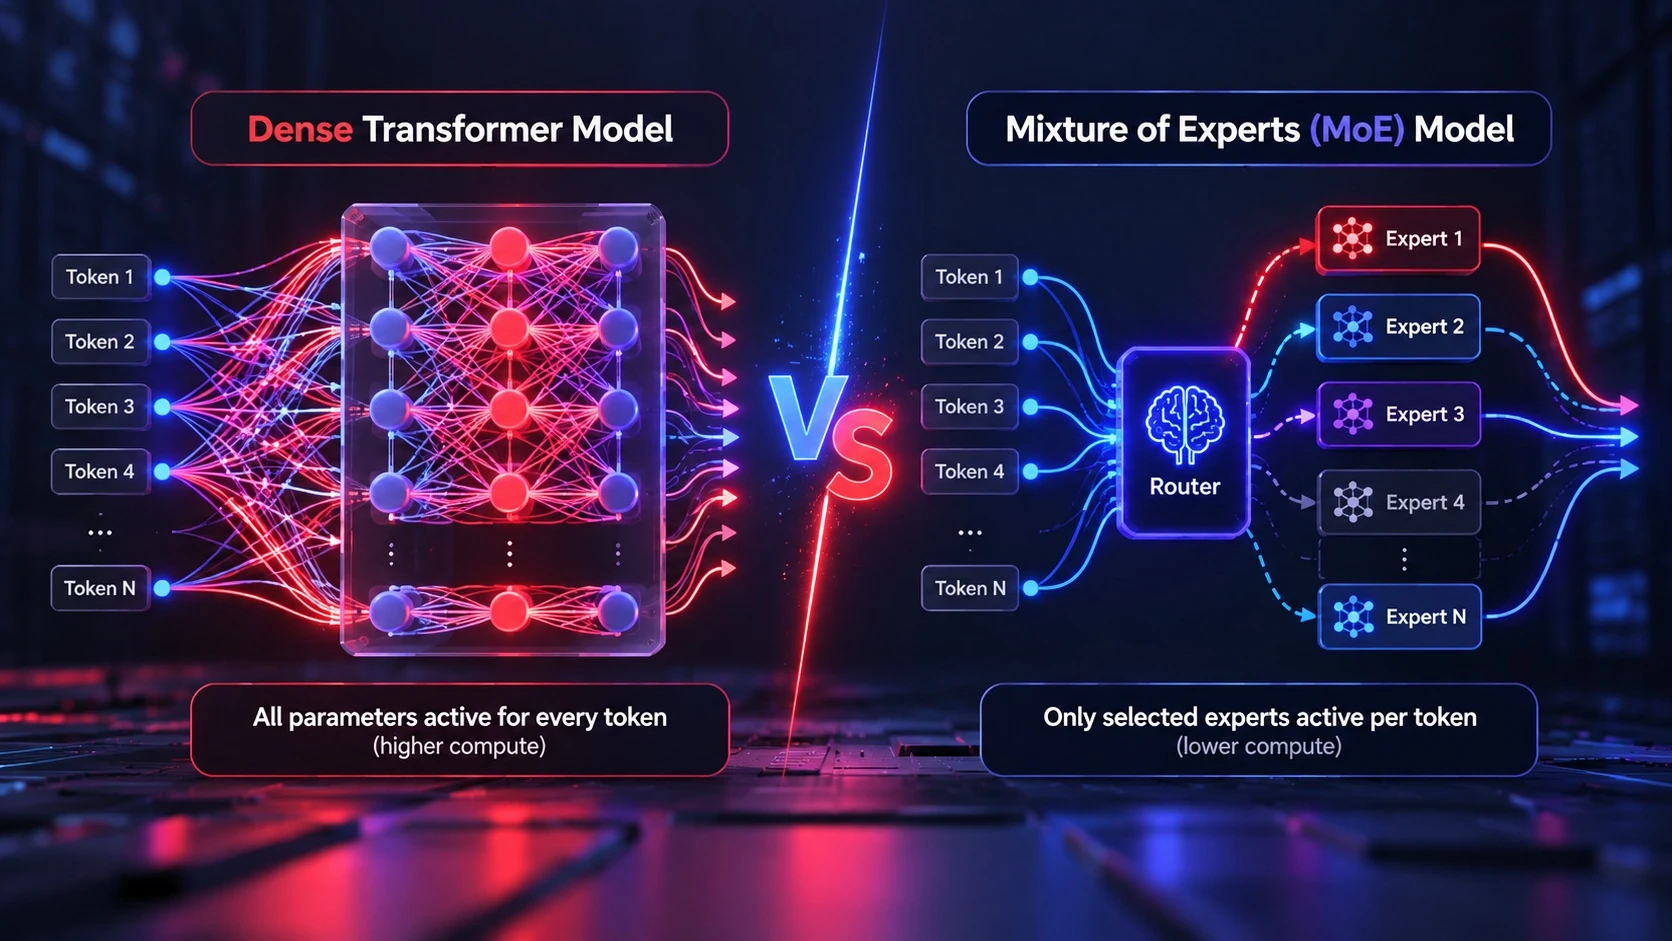
Dense models are simpler to train and deploy because every token follows the same path. MoE models are sparse during execution, which changes both performance behavior and operational complexity.
The tradeoff is not only speed versus size. It is also about stability, reproducibility, and serving reliability under real traffic patterns.
| Aspect | Dense Transformer | Sparse Mixture of Experts |
|---|---|---|
| Parameter Usage | The same dense layer weights are used for each token | Only selected expert parameters are activated for each token |
| Total Parameters | Closely tied to dense compute requirements | Can grow substantially without proportional growth in active compute |
| Routing | No expert-routing step | Router selects one or more experts |
| Training Complexity | Generally simpler | Higher because of routing, balancing and distributed communication |
| Serving Behavior | More uniform computation paths | Performance depends on routing, batching, expert placement and communication |
| Memory Requirements | Model weights must still be stored | Large total expert weights can create significant memory and distribution requirements |
Key Benefits of MoE Architecture
MoE is popular because it increases capacity while limiting cost. It can improve quality at a given compute budget, especially when trained at scale with strong data and infrastructure.
- More Capacity Without Linear Cost: Total parameters can grow while per token compute stays closer to a smaller model.
- Better Use Of Compute: Conditional activation focuses work on experts that matter for each token.
- Potential Quality Gains: Expert diversity can capture a wider range of linguistic patterns and reasoning behaviors.
- Modular Growth: Adding experts can expand capacity without redesigning the entire backbone.
These benefits are most visible when routing is stable and the system keeps experts well utilized.
MoE is only one approach to improving the relationship between model capability and computational cost. Another approach is AI model distillation, where a smaller student model is trained to reproduce useful behavior from a larger teacher model rather than selectively activating experts inside one large architecture.
Teams can also use AI model quantization to reduce the numerical precision of model weights and activations, addressing memory and inference efficiency without relying on sparse expert routing.
Common Challenges With MoE Models
MoE is not free performance. It introduces failure modes that dense models avoid, and it can shift bottlenecks from compute to communication and scheduling.
- Load Balancing: Routers can route a disproportionate number of tokens to a small set of experts, creating hotspots while leaving other experts underutilized.
- Training Instability: Sparse activation can increase variance and make optimization more sensitive.
- All-to-All Communication: When experts are distributed across devices, routing tokens to the appropriate experts can require substantial communication between accelerators, potentially reducing the computational savings of sparse activation.
- Serving Complexity: Efficient batching and consistent latency are harder when tokens activate different experts.These tradeoffs are documented in Switch Transformer research, which examines sparse routing alongside communication cost and training stability.
Most mature MoE implementations address these issues with auxiliary losses, capacity planning, and careful parallelism strategy.
Where MoE Fits in Modern AI Stacks
MoE is a good fit when the goal is to push quality while keeping marginal compute manageable. It is often used in large scale language models where training and inference cost dominates decision making.
In production, teams evaluate MoE systems not only by benchmark quality but also by throughput, active compute, total weight memory, communication overhead and operational predictability. Monitoring expert utilization, routing distribution, token capacity and latency is particularly important because an inefficient routing setup can erase part of the theoretical compute advantage.
MoE is generally aimed at scaling model capacity, but some deployment problems require the opposite strategy. Small language models prioritize compact runtime footprints and constrained hardware, making them more suitable when on-device memory, power consumption or offline inference matters more than maximizing total model capacity.
What to Consider Before Using MoE in Production
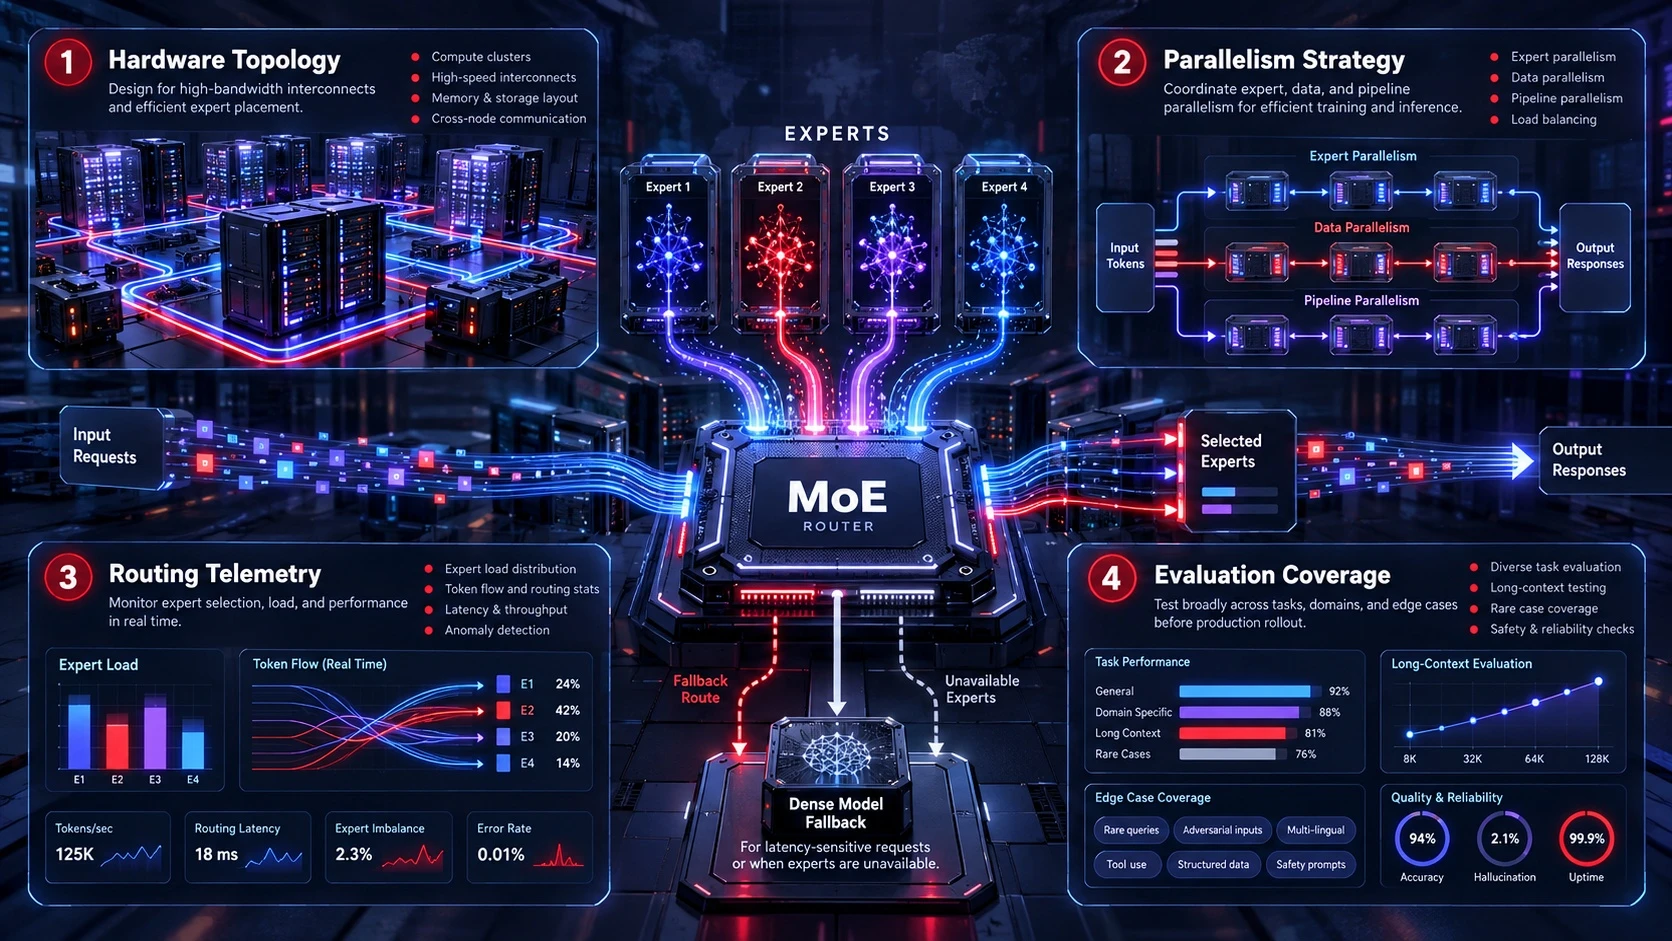
Adopting MoE affects data pipelines, distributed training setup, and inference serving. Planning around these constraints early avoids expensive rewrites later.
- Hardware Topology: Faster interconnects reduce routing overhead when experts span devices. Deployment architecture also matters outside the model itself; teams deciding where inference should run can separately compare local AI vs cloud AI based on latency, hardware capacity, privacy and operating cost.
- Parallelism Strategy: Expert parallelism and tensor parallelism must be coordinated to avoid bottlenecks. Distributed approaches such as GShard demonstrate how conditional computation and automatic sharding can be combined to scale sparse expert models across large accelerator clusters.
- Routing Telemetry: Tracking expert load and token drop rates helps catch quality regressions.
- Evaluation Coverage: Sparse models may behave differently on long contexts, rare domains, and outliers.
Teams also benefit from a clear fallback plan, such as a dense model option for latency-sensitive paths.
Conclusion
Mixture of Experts provides one way to increase an AI model’s total parameter capacity without activating every expert for every token. By using a router to select a small subset of experts, sparse MoE architectures can scale model capacity while limiting the amount of computation performed during each routing step.
The tradeoff is greater engineering complexity. Routing quality, expert load balancing, distributed communication, memory placement and serving latency all influence whether the theoretical efficiency gains appear in practice. MoE is therefore best understood not simply as a larger model for less compute, but as a different way of allocating computation inside large neural networks.
Frequently Asked Questions
Does MoE Always Make Inference Faster?
Not always. MoE reduces compute per token, but routing and cross device communication can add overhead. Real speedups depend on batching, hardware topology, and how experts are placed and parallelized.
How Many Experts are Typically Active for Each Token?
Most designs activate a small top k set of experts per token. Keeping k small preserves the compute advantage while still allowing diversity across experts. The best value of k depends on model size, data, and serving goals.
Why is Load Balancing Important in MoE?
If too many tokens route to the same experts, those experts become bottlenecks and other experts remain undertrained. Balancing improves throughput and helps the full parameter set contribute to quality. Many systems use auxiliary losses and capacity limits to encourage even utilization.
Does MoE Reduce the Total Memory Needed to Store a Model?
Not necessarily. MoE reduces the number of expert parameters activated for each token, but the complete set of expert weights still has to be stored somewhere in the system. Large MoE models may therefore require substantial GPU or accelerator memory across multiple devices even when their active computation per token is relatively low.