Running a small AI model offline allows you to generate text, summarize documents, and handle basic coding tasks directly on your laptop without depending on a constant internet connection. Once the required software and model files are downloaded, AI processing can take place locally without sending every prompt to a cloud server. With the right model size, sufficient RAM, and a suitable runtime, even an ordinary laptop can provide useful AI assistance without expensive hardware.
Before setting up offline AI, it helps to understand how small language models work on devices with limited processing power. These compact models are designed to handle language tasks while requiring fewer computing resources than many larger AI systems.
What Offline Local AI Really Means?
Offline local AI means the model weights are stored on your device, and inference runs on your CPU or GPU without sending requests to a hosted AI model. You generally need an internet connection to download the software and model files initially. As LM Studio’s official offline operation guide explains, downloaded models can run without internet connectivity, although downloading additional models, accessing online catalogs, and installing updates may still require a connection.
Running an AI model locally can reduce dependence on external servers, avoid hosted API rate limits, and give users greater control over their data. However, response speed still depends on the laptop’s hardware, model size, and available memory. For a detailed comparison of privacy, performance, and operating costs, explore our local AI vs cloud AI guide. Understanding these differences can help you decide whether an offline setup is suitable for your daily workflow.
Hardware Requirements for An Ordinary Laptop
Most modern laptops can run small AI models when they have enough available memory and a compatible local AI runtime. CPU-only inference is practical for many smaller quantized models, so a dedicated graphics card is not essential. However, laptops with compatible GPUs may generate responses faster, especially when the model fits in GPU memory. The amount of available RAM, GPU memory, and the model’s context length all affect performance.
Focus on memory first, then storage, then compute. Running out of RAM causes slowdowns that feel far worse than using a slower CPU.
- RAM: 8 GB can work for very small models, 16 GB is a comfortable baseline, and 32 GB helps with larger context windows.
- Storage: An SSD is recommended because AI model files can occupy several gigabytes. Faster storage helps when downloading and loading models, although response generation speed depends mainly on the processor, memory, and inference runtime once the model is loaded.
- CPU: Newer multicore CPUs handle token generation better, especially when using optimized backends.
- GPU: A compatible laptop GPU can accelerate inference, but offline setups still succeed without one. Available GPU memory matters as well as processing power.
Understanding the role of different processors can help you choose suitable hardware for running AI locally. Our CPU vs GPU vs NPU comparison explains how these processors handle different workloads and why some AI applications benefit from specialized acceleration. Once you understand your laptop’s capabilities, the next step is choosing a model that fits its available memory and processing power.
Choosing A Small Model That Fits
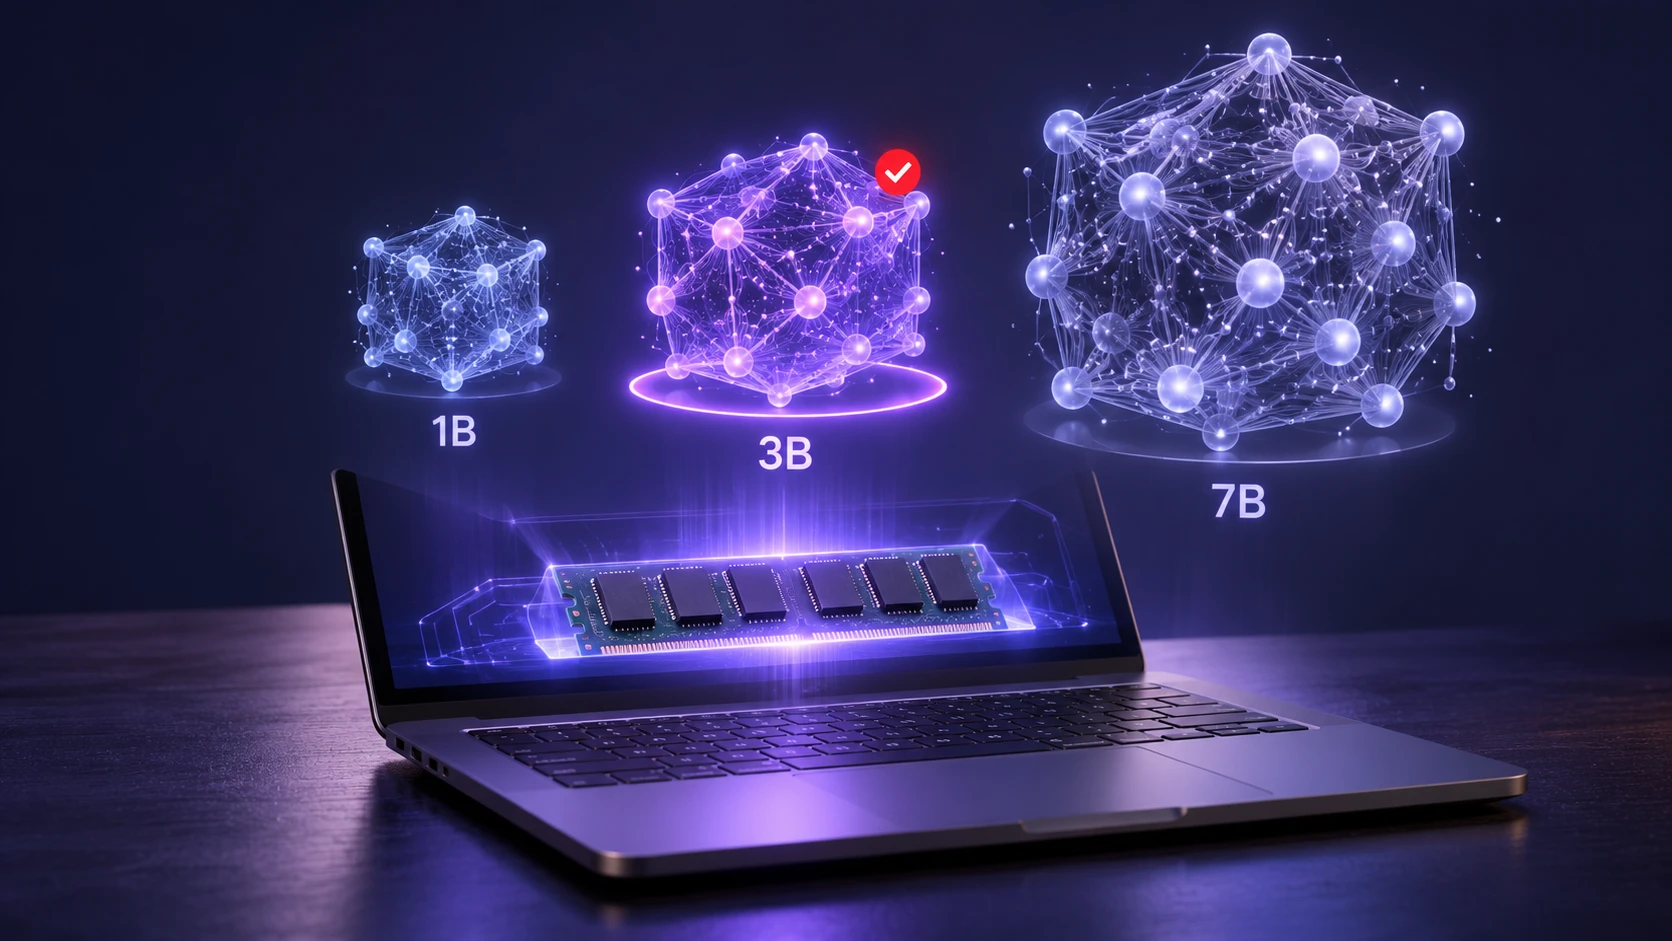
Small models typically fall in the 1B to 8B parameter range. For an ordinary laptop, the most reliable approach is to use a quantized model, which reduces memory footprint while keeping useful output quality.
Model choice should be guided by your main task. A compact instruction-tuned model is usually the best all-around choice for offline use.
Before downloading a model, check its file format, license, and compatibility with your chosen runtime. GGUF is a common format for local AI tools based on llama.cpp, while other runtimes may support different model formats. Also check the model’s download size and recommended memory requirements. A model that fits on your SSD may still need additional RAM or GPU memory during inference.
- General Assistant Use: Pick an instruction-tuned small model that follows directions well and stays coherent at short context lengths.
- Coding Help: Choose a code-focused model variant, but keep expectations realistic at very small sizes.
- Summarization and Notes: Prefer models that handle compression and structured outputs consistently.
- Low RAM Laptops: Favor smaller parameter counts and stronger quantization to avoid swapping.
Quality is not determined by parameter count alone. Quantization level, context length, and generation settings also affect a model’s performance and usefulness. For a practical beginner example, the Qwen3 1.7B model listing provides a compact quantized model that can be downloaded and run through Ollama. Start with a smaller model, evaluate its response quality, and move to a larger option only if your laptop has sufficient memory and processing power.
Understanding Quantization Without the Jargon
Quantization reduces the size of AI models by storing their numerical weights with fewer bits. Common options include Q4 and Q5 quantization, which can make larger models more practical on laptops with limited memory. The llama.cpp quantization documentation explains how lower-precision formats reduce model size and may improve inference performance. However, actual speed improvements and output-quality changes depend on the model, hardware, and quantization method.
Quantized models are particularly useful for offline laptop setups because they reduce memory requirements and can improve performance on supported hardware. If you want to understand the differences between precision levels and their effects on speed and accuracy, read our guide on AI model quantization explained. For everyday laptop use, choose a quantization level that fits your available memory while maintaining acceptable response quality.
Offline Runtimes and Tools You Can Use
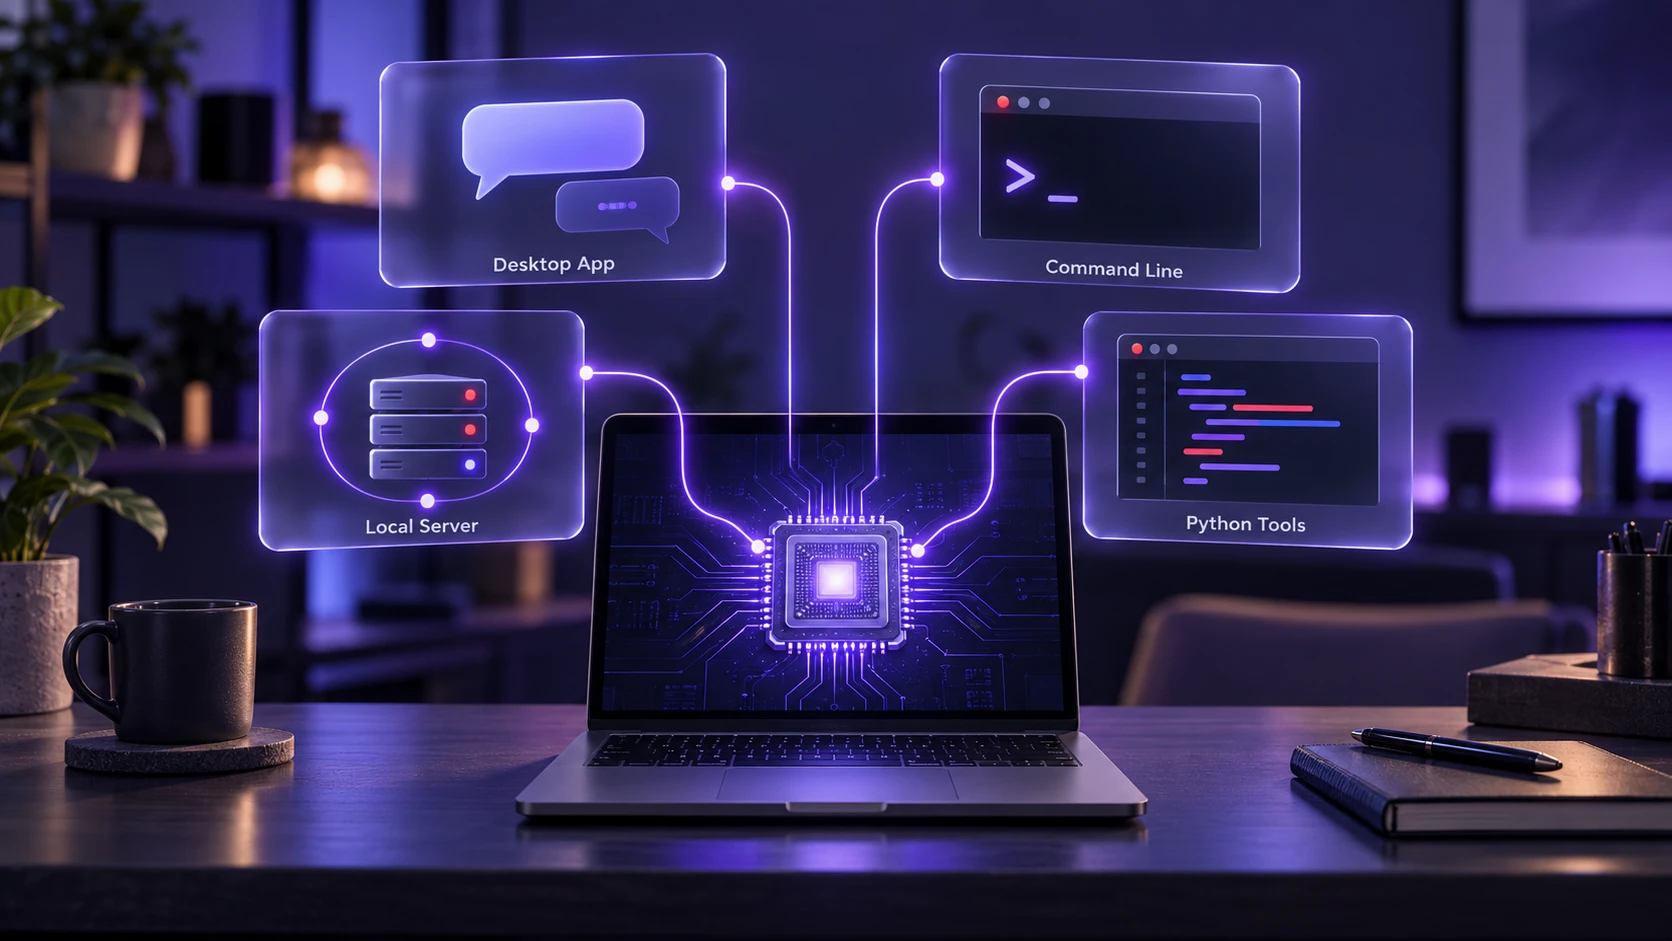
Several local runtimes make offline inference approachable. They typically handle model loading, tokenization, and optimized kernels, while offering a chat interface or a local server for apps.
For beginners who prefer a graphical interface, LM Studio’s getting-started guide explains how to download, load, and chat with local AI models. Users who prefer working through a terminal can visit the official Ollama download page to install a local AI runtime on Windows, macOS, or Linux. Both tools support running downloaded models locally, making them practical starting points for offline AI on an ordinary laptop. Always select a local model when your goal is offline inference.
- Desktop Apps: Provide one-click model management, a chat interface, and simple performance controls.
- Command-Line Runtimes: Offer advanced controls for threads, context length, and GPU offload.
- Local Servers: Expose an endpoint on your laptop so other local tools can send prompts without cloud calls.
- Python Tooling: Works well for custom workflows, batching, and integration into scripts.
After selecting a runtime, a clean install flow prevents common issues related to drivers, permissions, and memory limits.
Installing and Running Your First Offline Model
Keep the first run simple. Start with a small quantized instruction-tuned model, confirm it loads, then tune for speed and response quality.
Step 1: Check Your Laptop’s Available Memory
Close unnecessary applications and check how much RAM is available. For a first experiment, choose a compact model rather than downloading a large AI model that could exhaust your laptop’s memory.
Step 2: Install Ollama
Download and install Ollama for Windows, macOS, or Linux. Complete the installation while you have an internet connection and make sure the Ollama application or server is running.
Step 3: Download A Small AI Model
Open Terminal, Command Prompt, or PowerShell and enter:
ollama pull qwen3:1.7bThis downloads a compact quantized Qwen3 model to your computer. Its listed download size is approximately 1.4 GB, although additional memory is required when the model runs.
Wait until the download finishes before disconnecting from the internet.
Step 4: Run the AI Model Offline
Turn off Wi-Fi or disconnect your internet connection to confirm that the model works locally.
Open your terminal and enter:
ollama run qwen3:1.7bAfter the model loads, enter this test prompt:
Explain artificial intelligence in five simple sentences.The model should generate an answer directly on your laptop without using a hosted AI API. Type /bye when you want to leave the chat.
Step 5: Check Whether the Model Uses Your CPU or GPU
Open another terminal window while the model is loaded and enter:
ollama psThe output identifies loaded models and indicates whether they are using CPU memory, GPU memory, or both.
Step 6: Adjust Settings and Save Your Working Configuration
Start with a relatively short context window and increase it only if needed. If responses are slow or your laptop begins swapping memory to disk, try a smaller model or reduce the context length. Record the model name and settings that work best on your laptop.
Once you have a stable baseline, you can adjust settings to match your laptop and your specific tasks.
Settings That Matter Most for Laptop Performance
Most users get better results by tuning a few key controls rather than changing everything. The best settings are the ones that keep outputs consistent while staying within memory limits.
- Context Length: Longer context uses more memory and can slow inference, so increase it only when needed.
- Threads: Set threads to a sensible number for your CPU, often near physical core count for steady performance.
- GPU Offload: If available and supported by the runtime, offload some layers to the GPU for better tokens per second.
- Temperature: Lower temperature makes output less random, which can improve consistency for summaries and structured answers.
- Top-P: Helps control randomness alongside temperature, especially on smaller models.
These controls affect speed, memory use, and output quality in different ways. Making one change at a time keeps troubleshooting straightforward.
Recommended Starting Targets
The table below provides approximate starting recommendations for running quantized language models on ordinary laptops. These are general guidelines rather than guaranteed hardware requirements. Actual memory consumption depends on the model, runtime, context length, operating system, and available GPU memory. Begin with a smaller model and increase its size only after confirming stable performance.
| Laptop Profile | Suggested Starting Model | Quantization | What to Expect |
|---|---|---|---|
| 8 GB RAM, CPU Only | 1B–3B | Q4 | Basic text generation and short summaries |
| 16 GB RAM, CPU Only | 3B–7B | Q4 | General assistance and lightweight coding, with speed depending on the CPU |
| 16 GB RAM, With GPU | 3B–8B | Q4 | Potentially faster inference if GPU memory and runtime support are sufficient |
| 32 GB RAM, CPU Or GPU | 7B–13B | Q4–Q6 | More room for larger models, although CPU-only generation may remain slow |
These recommendations assume that enough memory remains available for the operating system and other applications. A model’s download size is not the same as its total memory requirement. Longer context windows also consume additional memory, so test your chosen configuration before relying on it for daily work.
After your first model runs smoothly, the next step is protecting privacy and keeping the local environment secure.
Privacy and Security for Offline AI
Running AI models locally can reduce the need to send sensitive information to external servers, but offline operation does not automatically eliminate security risks. Chat histories, saved prompts, and cached documents may remain on your device, making file permissions and local storage security important. Another concern is prompt injection, which can influence an AI assistant when it processes untrusted documents or instructions. Users should review generated responses and avoid granting local AI tools unnecessary access to sensitive files or applications.
Protect your offline AI setup with full-disk encryption, updated security software, and appropriate file permissions. Store sensitive documents and chat histories in protected locations, and avoid giving unnecessary applications access to them. When using a local AI server, keep it bound to localhost instead of exposing it to other devices or the public internet. Ollama’s official FAQ explains its default localhost configuration and how to disable optional cloud features when you want a local-only setup.
Common Problems and How to Fix Them?
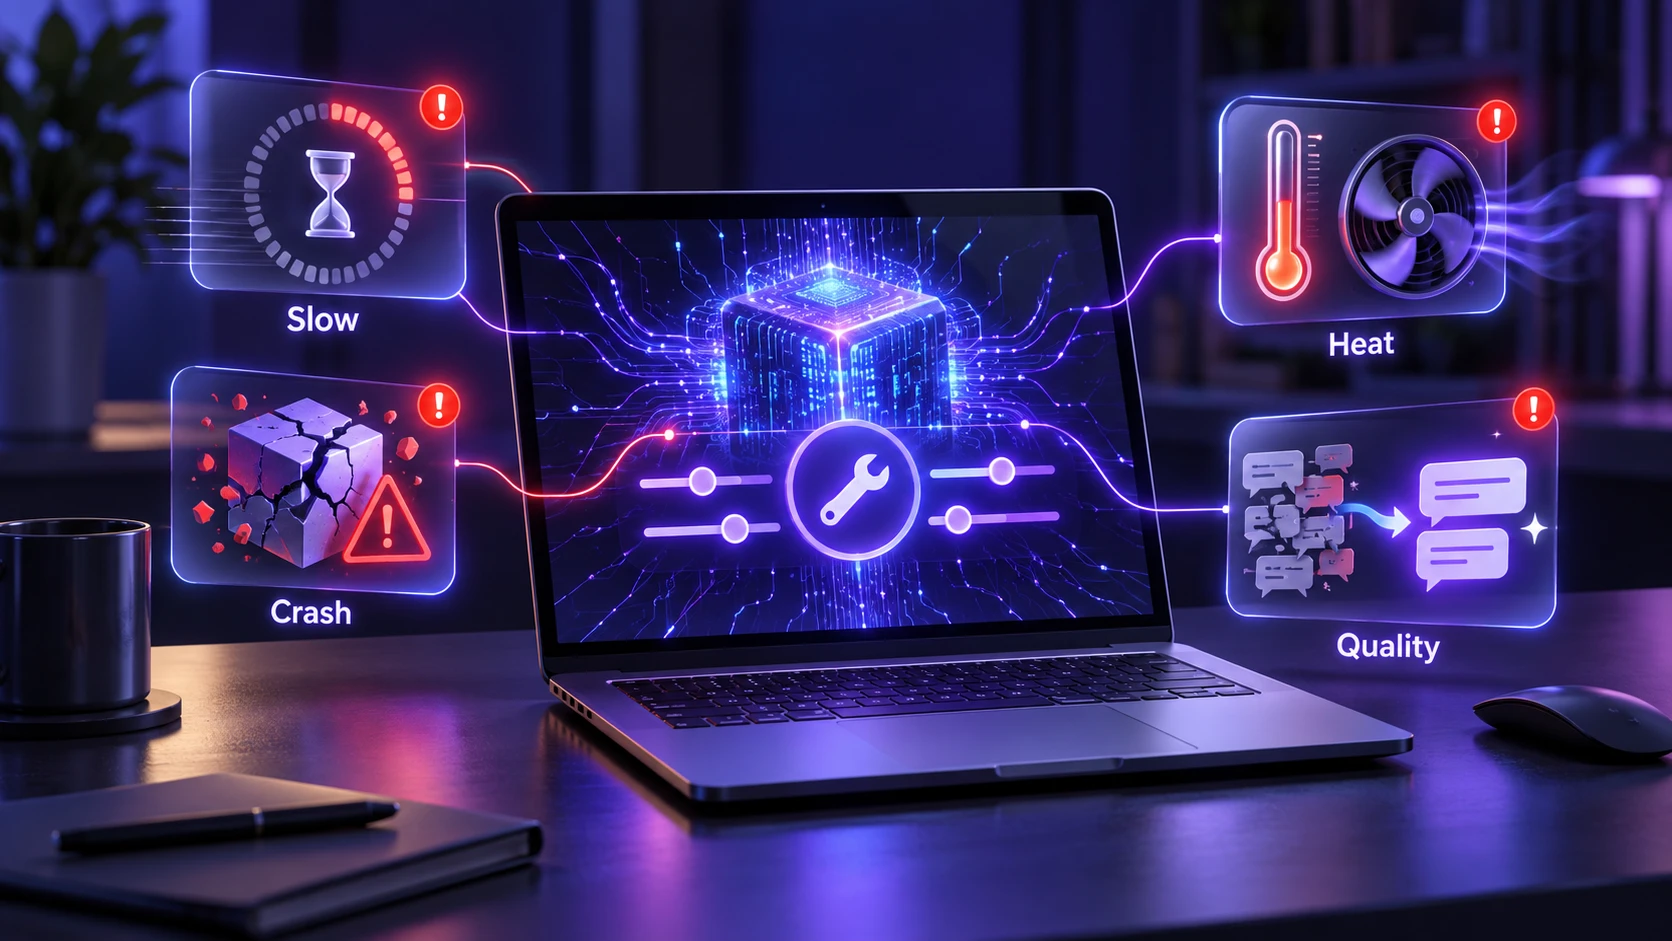
Most issues come from memory pressure, incompatible model formats, or overly ambitious context lengths. A small change usually fixes the root cause.
- Very Slow Responses: Reduce context length, lower model size, or switch to a more compact quantization level.
- App Crashes on Load: Confirm the model format matches the runtime and check available RAM before launching.
- Fan Noise and Heat: Lower threads, use a more conservative power mode, or shorten sessions to reduce sustained heat.
- Low Quality Output: Choose an instruction-tuned model, provide clear and specific prompts, and test different model sizes or quantization levels. Lowering temperature can make responses more consistent, but it does not guarantee factual accuracy. Always verify important information generated by a small local AI model.
If you want a smoother setup, TechBonafide’s practical approach is to start with a stable baseline configuration and then scale up cautiously as your laptop proves it can handle more.
How to Keep Offline Models Useful Over Time?
Offline models become more useful when your workflow improves. Maintain a small set of prompt templates for recurring tasks like summaries, checklists, and code review notes.
Keep model files organized, track which presets work best, and periodically test a newer small model version if it offers better instruction following at the same size. Stability and repeatability matter more than chasing the biggest model your laptop can barely load.
Conclusion
To run a small AI model offline on an ordinary laptop, choose a realistic model size, use quantization, and tune context length and threads for steady performance. Prioritize RAM and SSD storage, then use GPU acceleration if your machine and runtime support it.
A local setup can provide greater control over prompts and files while reducing dependence on external AI services. With a stable runtime, suitable model, and sensible settings, an ordinary laptop can handle useful everyday AI tasks even when it is disconnected from the internet.
Frequently Asked Questions
What is the Best Small Model Size for An Ordinary Laptop?
The best small AI model depends on your laptop’s available RAM, processor, and intended tasks. For an 8 GB laptop, a quantized model with around 1B to 3B parameters is a sensible starting point. A laptop with 16 GB RAM may handle a 3B to 7B quantized model, although performance varies by CPU, context length, and background memory use. Start small and increase model size after testing speed and stability.
Can I Run A Small AI Model Offline Without A GPU?
Yes, CPU-only inference is common and can be very usable with a quantized model. Performance depends on your CPU cores, memory bandwidth, and context length. Keeping prompts concise and limiting context size helps a lot on CPU.
How Do I Keep My Offline AI Setup Private?
Run inference locally, store models and sensitive files on an encrypted drive, and keep chat logs in a controlled location. If you use a local server mode, bind it to localhost so it is not reachable from other devices. Regularly review app settings that control history, telemetry, cloud features, and network access.