SRE and DevOps are often discussed as competing models, but they are better understood as complementary approaches to building and running reliable software. Both focus on faster delivery with fewer failures, yet they differ in how they define reliability, enforce operational discipline, and measure success. Understanding where they align and where they diverge helps leaders set clear ownership, avoid duplicated effort, and improve service stability.
DevOps and SRE in Simple Terms
DevOps is a culture and operating model that brings development and operations closer through shared ownership, automation, and continuous delivery. It aims to reduce friction between building software and running it in production. When DevOps is working well, teams ship more frequently while maintaining steady performance and availability. Google’s guide, How SRE Relates to DevOps, explains how SRE applies many DevOps principles through specific engineering and operational practices.
Site Reliability Engineering, or SRE, is an engineering discipline that applies software practices to operations work. It treats reliability as a product feature with explicit targets and measurable risk. SRE teams use concepts like service level indicators (SLIs), service level objectives (SLOs), and error budgets to decide how much change a system can safely absorb.
Core Goals and Success Metrics
DevOps typically focuses on improving software delivery, reducing delays, and strengthening feedback between teams. According to DORA’s software delivery performance metrics, teams can evaluate delivery performance using five measures: change lead time, deployment frequency, failed deployment recovery time, change fail rate, and deployment rework rate. Together, these measurements help teams understand both delivery speed and stability.
SRE tends to optimize reliability outcomes. It sets clear service level objectives and continuously evaluates whether systems are meeting those targets. Metrics often center on availability, latency, and incident impact, along with error budget burn and toil levels.
How SLOs and Error Budgets Work in Practice?
A service level indicator (SLI) measures an aspect of a service’s performance, such as the percentage of successful requests. A service level objective (SLO) sets a target for that measurement over a specific period.
For example, suppose an online application has an SLO requiring 99.9% of eligible requests to succeed over 30 days. If the application receives one million eligible requests during that period, its error budget allows up to 1,000 unsuccessful requests before the target is missed.
If failures begin consuming that budget too quickly, engineering teams can prioritize reliability improvements, investigate the causes, or slow risky releases according to an agreed policy.
This example shows how SRE teams use measurable reliability targets to make practical engineering decisions. For additional guidance on selecting indicators, setting targets, and using error budgets, see Google’s guide to implementing SLOs.
Typical DevOps Responsibilities Across Engineering Teams
DevOps responsibilities are shared across development, operations, and platform engineering teams, depending on how an organization works. These responsibilities generally support continuous integration, continuous delivery, infrastructure automation, and safe software releases. Some organizations have dedicated platform or DevOps enablement teams, while others distribute the work across product teams. The goal is to make software delivery faster, safer, and more consistent.
- CI/CD Enablement: Build and maintain pipelines, quality gates, and release automation that reduce manual steps.
- Infrastructure Automation: Use infrastructure as code to provision environments consistently across development, staging, and production. Our Terraform vs. OpenTofu comparison explains how two infrastructure automation tools compare in features, licensing, and workflows.
- Developer Platform Support: Provide self-service tooling for builds, deployments, secrets, and environment configuration.
- Release and Change Practices: Standardize branching, versioning, deployment strategies, and rollback expectations.
- Operational Readiness: Ensure services have logging, monitoring, and runbooks before they go live.
These areas reduce bottlenecks and make delivery repeatable, especially as teams and services scale. Teams that want to understand different deployment approaches can also explore how GitOps and CI/CD work together to automate software delivery and manage infrastructure configuration.
Typical Responsibilities in An SRE Team
SRE responsibilities are shaped by reliability objectives. The goal is to keep services within agreed targets while controlling operational workload. SRE teams often act as reliability stewards across multiple services or a critical platform.
- Service Level Management: Define SLIs and SLOs, track compliance, and align reliability targets with product goals.
- Incident Response and Learning: Help establish clear on-call responsibilities, support incident coordination, and review failures to prevent repeated problems. Google’s guidance on blameless postmortem practices explains how teams can learn from incidents and turn findings into meaningful improvements.
- Toil Reduction: Identify repetitive, manual operational work and reduce it through automation, improved tooling, or better system design. Google’s guidance on eliminating toil explains why reducing this workload allows engineers to spend more time on improvements that scale.
- Capacity and Performance Planning: Forecast growth, validate scaling behavior, and prevent resource exhaustion and bottlenecks.
- Reliability Engineering: Improve resilience through redundancy, safer rollouts, and failure testing practices.
This set of responsibilities makes reliability measurable and keeps operational risk within agreed boundaries.
Where SRE and DevOps Overlap?
The overlap is real and substantial. Both disciplines rely on automation, observability, and continuous improvement. The difference is often the primary driver, with DevOps emphasizing delivery flow and SRE emphasizing reliability targets.
- Automation: Both reduce manual work with scripts, pipelines, and infrastructure as code.
- Observability: Both invest in metrics, logs, traces, and alerting to understand system behavior and investigate failures. SRE practices may also use SLO-based alerting to identify problems that threaten reliability targets or consume error budgets too quickly.
- Operational Excellence: Both raise standards for runbooks, incident handling, and post-incident improvement.
- Cloud and Kubernetes Operations: Both contribute to cluster reliability, rollout safety, and cost awareness.
- Security and Compliance Alignment: Both collaborate with security teams to build secure-by-default delivery workflows and access controls. Practices such as automated secrets management can help teams manage sensitive credentials and reduce unnecessary exposure across deployment systems.
When overlap is explicit, it strengthens shared ownership rather than creating ambiguity. For example, understanding the difference between observability and monitoring can help engineering teams decide which information they need to detect problems and investigate system behavior.
Key Differences in Mindset and Approach
DevOps is often implemented as a transformation initiative. It shapes how teams collaborate, how work moves from idea to production, and how feedback is captured and acted on. It also encourages product teams to own the full lifecycle of the services they build. For a broader introduction to collaboration, automation, and continuous delivery, explore our guide to DevOps principles and practices.
SRE is typically implemented as a specialized reliability function or through reliability practices adopted within product teams. It introduces shared reliability targets through SLOs and uses error budgets to balance innovation and stability. That structure helps resolve common conflicts between speed and safety with shared data instead of opinions.
How Ownership and Team Boundaries Usually Work?
In many organizations, DevOps work is supported by a platform or enablement team that builds shared tooling. Product teams then use that platform to deploy and operate services. This model works best when the platform team treats internal teams as customers and maintains strong documentation and support workflows.
SRE responsibilities can be handled by centralized reliability teams, engineers embedded within product teams, or product teams that adopt SRE practices themselves. Centralized SRE teams may define reliability standards, support incident response, and help critical services meet agreed objectives. However, on-call ownership should be assigned explicitly because SRE teams do not automatically operate every service. Embedded reliability engineers can work closely with developers to improve system design, deployment safety, monitoring, and incident readiness.
Skills and Tooling That Commonly Appear in Both
Tools do not define DevOps or SRE, but certain capabilities show up repeatedly. Many teams adopt similar foundational tooling as systems become more distributed and complex. What changes is the emphasis on how those tools are governed and used.
- Version Control and CI Systems: Standard workflows for code review, automated tests, and build artifacts.
- Infrastructure As Code: Reproducible environments and auditable change history for infrastructure.
- Containers and Orchestration: Consistent application packaging and scheduling, often using containers, Kubernetes, and related orchestration tools.
- Observability Stack: Metrics, logs, traces, dashboards, and alert routing with clear ownership.
- Release Safety Controls: Use progressive delivery, feature flags, deployment health checks, and automated rollback signals to reduce release risks. Our comparison of blue-green and canary deployment strategies explains how teams can limit disruption when deploying application changes.
As maturity grows, the focus shifts from tool adoption to disciplined use, clear standards, and measurable outcomes.
SRE Vs. DevOps: Side-By-Side Comparison
Comparing the two directly can clarify where to place responsibilities and how to measure progress. Effective organizations borrow from both approaches and adapt them to their architecture, risk profile, and business priorities.
| Comparison Factor | DevOps | SRE |
|---|---|---|
| Primary Focus | Improve collaboration and software delivery | Maintain measurable service reliability |
| Main Goal | Deliver software safely and efficiently | Keep services within agreed reliability targets |
| Core Practices | CI/CD, automation, shared responsibility | SLOs, error budgets, incident management |
| Success Metrics | Deployment frequency, change lead time, and change stability | SLO compliance, error budget consumption, incident impact |
| Automation | Automates delivery, testing, and infrastructure workflows | Automates repetitive operations and reliability tasks |
| Incident Management | Encourages shared operational responsibility | Emphasizes measurable response, recovery, and learning |
| Team Structure | Practices can span product, operations, and platform teams | Reliability practices can be centralized, embedded, or shared |
| Release Decisions | Uses testing and deployment safeguards | Uses reliability objectives and error-budget policies to guide risk decisions |
| Best Suited for | Improving software delivery and collaboration | Managing operational risk with explicit reliability targets |
When to Choose SRE, DevOps, or Both
DevOps is a strong starting point when teams struggle with slow releases, inconsistent environments, and handoff friction. It helps organizations adopt continuous delivery practices and reduce the gap between development and operations. DevOps also fits well when product teams are expected to own their services end-to-end.
SRE practices become especially valuable when teams need clear reliability targets and a consistent way to manage operational risk. They are useful for high-traffic applications, business-critical services, and systems with complex dependencies. However, smaller teams can also benefit from defining basic SLOs, improving alerts, documenting incident responses, and reducing repetitive operational tasks. A dedicated SRE department is not necessary to begin applying these principles.
Using both works well when you want fast delivery and strong reliability guardrails. DevOps practices can build the foundation, while SRE adds measurement and risk management. The combined model can help organizations maintain reliable services as their systems and operational needs grow.
Reducing Friction Between Teams
Confusion usually comes from unclear ownership. If multiple teams maintain pipelines, alerts, and production runbooks without a shared model, duplication and gaps can appear. Clear boundaries and shared standards help address these issues.
- Define Service Ownership: Assign a primary owner for each service and a clear escalation path for incidents and reliability work.
- Agree on Reliability Targets: Use measurable indicators and objectives so everyone knows what good looks like.
- Establish Shared Release Standards: Define consistent expectations for code reviews, automated testing, deployment checks, and rollback procedures. Teams can use different deployment workflows when necessary, provided they follow agreed security and reliability requirements.
- Align on Observability Standards: Decide what metrics, logs, traces, and alerts are required before production.
- Review Toil and Incident Trends: Track operational load and prioritize automation and engineering work that removes repetitive problems.
With these practices in place, teams spend less time negotiating responsibilities and more time improving systems.
How to Apply DevOps and SRE Together in Practice?
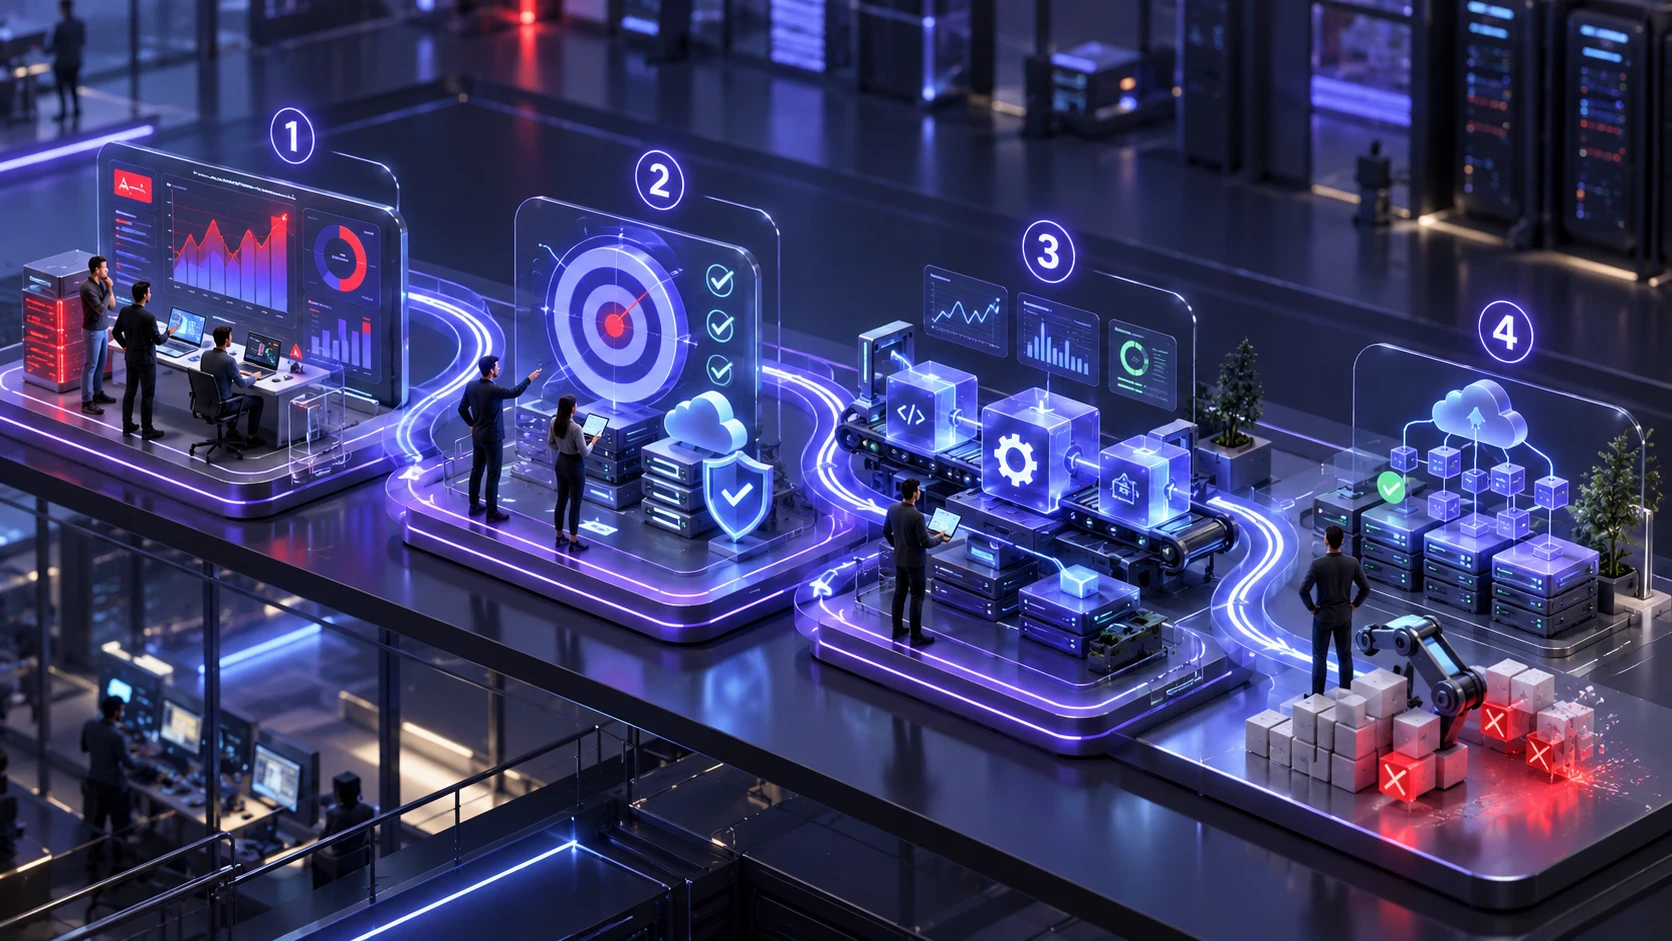
Organizations can combine DevOps and SRE practices without creating unnecessary teams or complicated processes. The best approach is to begin with existing delivery and reliability problems, establish clear ownership, and introduce improvements gradually.
A practical implementation can follow these steps:
- Evaluate Current Delivery Practices: Review release frequency, testing, deployment failures, and the time required to restore affected services.
- Define Reliability Targets: Select important user-facing indicators and establish realistic SLOs for critical services.
- Improve Automation and Monitoring: Strengthen CI/CD pipelines, infrastructure automation, service monitoring, and incident alerts.
- Review Results and Reduce Toil: Track delivery performance, reliability outcomes, and repetitive operational work. Prioritize improvements based on measurable results.
Teams should begin with one important service, evaluate the results, and expand successful practices to other applications.
This gradual approach helps organizations improve delivery speed and reliability while keeping responsibilities clear.
Conclusion
DevOps and SRE share the same goal: delivering high-quality software efficiently while keeping services reliable. DevOps emphasizes collaboration and delivery flow, while SRE formalizes reliability targets and uses engineering to manage operational risk. The overlap is a strength when ownership is clear and standards are shared.
If releases are slow and manual, start by strengthening DevOps practices and platform foundations. If incident load and reliability risk are the main blockers, add SRE concepts like SLOs, error budgets, and toil reduction. Most teams benefit from a blended approach that keeps delivery fast and reliability measurable.
Frequently Asked Questions
Is SRE A Replacement for DevOps?
No. SRE is a specific engineering discipline focused on reliability, while DevOps is a broader cultural and operational model. Many organizations use DevOps practices across teams and apply SRE methods where reliability needs are highest.
Can A Small Team Do SRE Without Hiring A Dedicated SRE Team?
Yes. A small team can adopt SRE concepts by defining a few key SLIs and SLOs, improving alert quality, and tracking toil. Dedicated SRE roles may become useful when systems scale and incident management demands more consistent engineering attention, but they are not required to begin.
What is the Clearest Sign That You Need SLOs?
If teams regularly disagree about whether a service is reliable enough, they likely need SLOs. SLOs turn reliability into measurable targets that support better prioritization. They also help balance feature delivery against stability work with a shared view of risk.